The Decision Authority Placement Model (DAPM)
Version 2, September 2026
Version 1 was published December 2025. Version 2 reconciles it with the applied work since, and with the vendor instrument, reconciled to it in the same release. Two outside models reviewed each draft; the reconciliations are published alongside.
Abstract
Enterprises keep hitting the same failures every time they automate, and they keep blaming the wrong thing: the tools, the skills, the governance. Systems are making runtime tradeoffs, and nobody decided who was allowed to make them.
The Decision Authority Placement Model (DAPM) is a technology-agnostic framework for finding where decision authority sits and whether accountability is anchored to it. Version 1’s core claim has held: automation gets adopted for its execution benefits while authority placement stays implicit until a failure forces it into view.
What didn’t hold was the vocabulary. Authority is placed at a boundary, in one of three placements: Retained, Delegated, or Ceded. The three modes in v1 were those placements at the organizational boundary. It applies between a human and a model, and between an enterprise and a vendor, and one three-part question decides it at all three.
Version 2 adds what the lab found: the validator that decides “done” holds authority, human escalation in the critical path collapses under decision frequency, and authority may drift silently when a model gets better. It names a property v1 had no word for, portability, and keeps it out of the thesis. And it drops the claim to be diagnostic in favor of an operating model. DAPM prescribes four things: authority explicitly placed at a named boundary, accountability anchored to it, an override path for every delegation, and evidence the placement held. When execution is automated and authority stays implicit, failure isn’t an anomaly. It’s the design.
1. Why a second version
I published DAPM to explain a pattern I’d been writing about since a July 2012 post arguing that deploying SDN is easy and fixing your IT organization is hard: virtualization exits, cloud migrations, platform engineering, and now agentic AI, all with the same failure signature. Loss of control. Governance backlash. Cost surprises. The paper said these weren’t execution failures. They were authority failures, and the authority had never been placed.
Then I spent the months since December using it, on my own workflow, on a government contract dispute, in the lab, and on an instrument that scored 28 vendors across eight infrastructure layers. Every exercise confirmed the core claim, and most used words the paper doesn’t contain. “Retained, Delegated, Ceded” became what people think DAPM says, and the three modes I actually published went dormant in my own writing. The applied work found something simpler than the theory. This version brings the theory up to it.
2. Definition
DAPM is a framework for understanding who is authorized to make tradeoffs at runtime when enterprise systems act without a human in the path of each decision. It focuses on placement: where authority is deliberately assigned, implicitly inherited, or accidentally displaced as systems automate behavior.
Four things about the model haven’t changed since v1. It’s technology-agnostic: it applies to a storage array’s tiering policy and to an agent’s tool selection. It doesn’t care which way you’re moving: a cloud migration and a cloud exit raise the same question. It keeps execution and authority apart: the thing that runs a decision is not the thing that was authorized to make it. And it treats accountability as a design concern, not a cleanup task: placement is a choice someone made, or failed to make.
Terms this paper leans on, glossed once. The 4+1 Layer AI Infrastructure Model is my map of the enterprise AI stack: compute and fabric at Layer 0, the data plane at Layer 1, the operational plane at Layer 2 with control, execution, and reasoning sub-planes, and applications at Layer 3, the plus one. Layer 2C is the reasoning sub-plane, where placement decides which model runs, under what policy, and whether the output passes. Auditable Authority is the design companion to this paper. The vendor instrument is a public assessment of 28 infrastructure vendors against the 4+1 model at layer2c.com.
2.1 What counts as DAPM
Version 1 spawned offspring, so the paper has to say what an application keeps to carry the name. Core DAPM is this paper. It keeps the four things above and adds three rules: placed on purpose versus unplaced comes first, and unplaced is never a mode; an accountability anchor is named; and, new in v2, the placement is named at a stated boundary, with a litmus for that boundary. DAPM-derived applications keep all of that and specialize the litmus for one boundary: Auditable Authority at the human-to-model boundary, and the vendor instrument, as of this revision, at the enterprise-to-vendor boundary. DAPM-compatible applications keep the vocabulary and some of the properties, and say which.
3. Boundary, anchor, gap
Authority doesn’t go unplaced. You can make compromises based on design constraints such as lack of funding or technical talent; authority placement doesn’t care. It’s a design choice whether implicit or explicit. The difficulty is in naming the boundary. Let’s use a common example to show the boundary.
Your organization may be structured with a network, storage, and virtualization group. You’ve been directed to implement a fourth cloud solution. You select VMware Cloud Foundation (VCF) as the reference architecture. It provides the ability to create virtual networks straight from a developer request – the automation.
The failure mode, if you haven’t already predicted it, is at the boundary between the virtualization and network teams. Who decides when a switch state configuration changes or reverts? In the previous manual system, it wasn’t even a question on the intake form. It’s something that an engineer decided based on some unwritten rule.
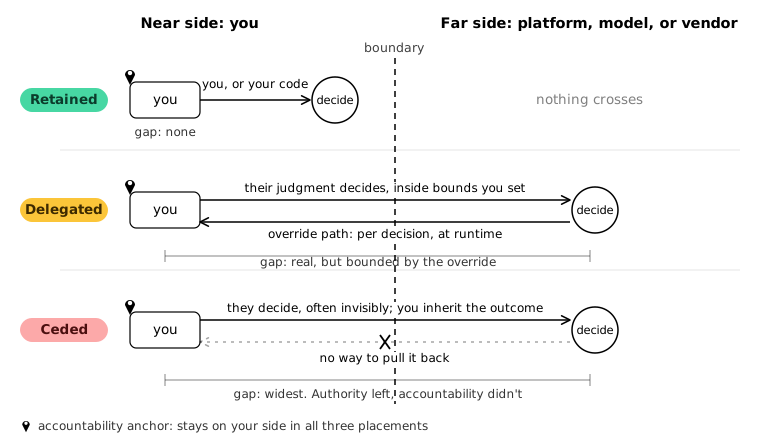
The authority was ceded to VCF implicitly. However, accountability never changed. The network team is still accountable for the network configuration and management but authority for the change has been ceded to a system, VCF, without accountability changing. The network team is the accountability anchor: the people who answer for the outcome. The distance between where the authority went and where the accountability stayed is the DAPM Gap, and it’s where the failures in the rest of this paper come from.
Name the sides and the case reads cleanly. The network team is the near side of the boundary. The virtualization team’s platform is the far side. The vendor behind the platform is a further boundary, and section 9 covers it. The same three probes, can the near side see the decision, override it, and reach the decider with accountability, apply between a human and a model and between an enterprise and a vendor, and 4.1 lays them out. The placement is defined by those probes, so it holds wherever they can be asked, and the instrument asked them across 224 layer cells.
4. Placement
What this paper calls unplaced authority is authority nobody placed on purpose. Leaving it unplaced is itself a decision, and someone answers for it. It came down from upstream platforms, vendor defaults, and the way things were run before. Systems make runtime tradeoffs because they must, so authority is assumed rather than assigned, and accountability stays with the organization while the authority sits in the technology. Unplaced isn’t an operating mode. It’s the absence of one, and most enterprise IT failures happen here.
Once authority is explicitly placed at a boundary, it’s in one of three placements. Two of them cross the boundary. One doesn’t.
Retained. Authority stays on the near side. The human decides. The product team decides. The enterprise makes the runtime tradeoff itself, or code the enterprise writes and controls makes it, wherever that code runs. If you wrote the policy and the vendor’s deterministic engine only evaluates it, you decided. Retained is a verb somebody did. It’s never a default.
Delegated. Authority crosses under a bounded, revocable grant. The human sets policy and the system’s judgment executes within it. The team decides within guardrails the platform set. The vendor’s or the model’s judgment makes the call, inside bounds the enterprise set and can override at runtime. What makes a delegation real is the override path, and that path is per decision, at runtime: change the policy, pull the decision back, refuse the action. Being able to leave the vendor altogether is a different property, and section 9 has it. Delegation without an override path is cession with a friendlier name.
Ceded. Authority crosses with no way to pull it back. The model decides autonomously. The platform decides and the team consumes the result. The vendor decides, often invisibly, and the enterprise inherits the outcome. Ceded isn’t pejorative. It describes the governance relationship, not fitness for purpose.
None is inherently superior. Failures come from placing implicitly or misaligning placement with accountability.
4.1 One question at three boundaries
| Boundary | Near side | Far side | The litmus for Ceded | Where it’s worked out |
|---|---|---|---|---|
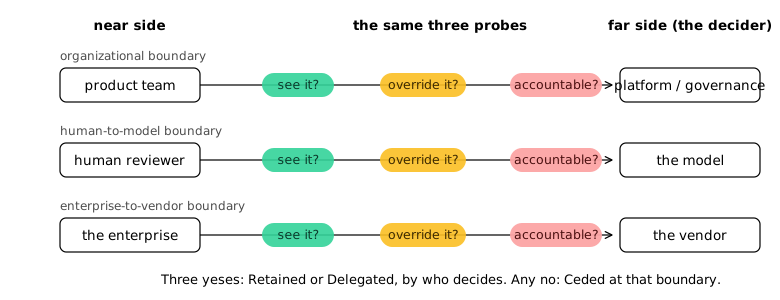
| Organizational | Product team | Platform or governance function | Can the team see the platform’s decision, override it, and hold a named function accountable for it? | This paper, v1 |
| Human to model | Human reviewer | The model | Can the reviewer inspect the decision path, override it, and stand as the accountable party for what the model decided? | Auditable Authority |
| Enterprise to vendor | The enterprise | The vendor | Can the enterprise see the vendor’s runtime decision, override it, and reach the vendor with accountability for it, while the anchor stays on its own side? | The vendor instrument, per layer |
It’s one question: can the near side see the decision, pull it back, and reach the decider with accountability? What differs is who the decider is. A product team that can read the platform’s logs but can’t override its scaling decisions has operational control, not authority. So does an enterprise running a vendor’s autonomous database that tunes itself with no policy input.
4.2 The v1 modes were the three placements, applied once
| v1 mode | What it described | Placement |
|---|---|---|
| Platform-Led | The platform decides and enforces within bounds | Ceded to the platform |
| Product-Aligned | Teams decide within guardrails the platform set | Delegated to the team |
| Governance-Coupled | Automation runs until a threshold, then a governance body decides | Delegated to the system, with the override retained by governance |
Governance-Coupled is the row to be honest about. Below the threshold the system decides, continuously. Above it a human does. That’s a delegation with a retained override, not retention, and calling it “retained” would erase the automation doing most of the deciding. It’s also why that mode fails at tempo (section 7). I named where authority landed when I should have named the placement.
The Authority Matrix, v1’s artifact for making placement explicit per decision domain, gains columns for boundary, placement, compute model, inspectability, and evidence. It’s in the appendix with the assessment questions.
5. Failure modes as placement mismatches
DAPM predicts failure from mismatches between where authority sits, how it got there, and where accountability is expected to live. Version 1’s five modes survive as signatures. The applied work added two, and section 6 adds a third.
| Mismatch | Signature |
|---|---|
| Unplaced authority, organizational accountability | Systems behave correctly but unpredictably. When the outcome is questioned, nobody owns it. |
| Ceded authority, retained accountability | The platform decides, the team answers. Loss of trust, defensive architectures, over-provisioning. |
| Human escalation under continuous automation | Escalation overload, bottlenecks, manual controls reintroduced. Section 7 restates the claim. |
| Delegated authority without shared guardrails | Behavior fragments, risk posture diverges. At the model boundary the guardrails are validators and policy code. |
| Boundary friction | Locally rational placements fail at the seams, where one layer’s decision triggers consequences governed by another’s placement. The dominant source of instability in layered systems, now across all three boundaries. |
The second row crosses the vendor boundary intact, and the instrument now scores it: 123 of 224 layer cells read Ceded on decision authority, the vendor or a model deciding with no enterprise override. Fourteen of those are gap cells, mostly at Layer 0 and 2A, where the vendor absorbs the layer beneath its own service and the enterprise can’t see the decision. The instrument scores authority. It doesn’t score where accountability went. The row narration implies it stayed with the enterprise, and that inference hasn’t been scored.
5.1 Oscillation, the visible response
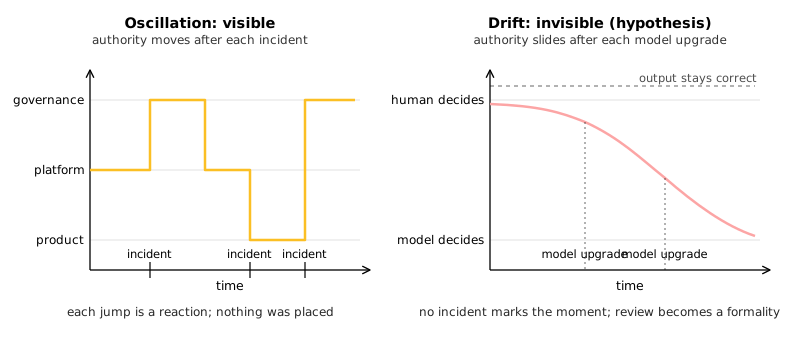
When systems fail and no placement was made on purpose, organizations reassert control by moving authority around: to governance after the incident, back to the platform to restore velocity, out to product to unblock delivery. Each shift addresses a symptom locally and increases global instability. Oscillation is an attempt to re-anchor accountability after a widened DAPM Gap has been exposed, and it persists until authority and accountability are explicitly aligned. Version 1 called it the dominant response. That stands for the failures anyone can see.
5.2 Drift, the invisible one (hypothesis)
This is a failure mode the paper missed, and my own workflow is where I found it. One case is enough to describe a mechanism. It isn’t enough to say how common it is, so treat this as a hypothesis with a test attached.
Oscillation is visible thrash after an incident. Drift is invisible erosion after an improvement. When a model upgrade makes AI output better, the AI implicitly assumes authority over parts of the workflow that were never assigned to it. The output quality makes the assignment feel legitimate, so the review that used to be a decision becomes a formality. Output stays correct. What changes is who’s actually deciding, and there’s no incident to mark the moment. Metrics that depend on judgment rather than correctness degrade slowly. In my case, the drafts got better and audience growth slowed, and it took months to connect the two. The fix was a placement, written down: the AI co-authors formal documents and is advisory only for editorial work. An organization that placed authority once and never revisited it is drifting back to unplaced, and the model’s improvement is what’s moving it.
What would confirm this: several organizations where a capability upgrade measurably changed who reviews what, before any incident, with the external drivers of the outcome metric controlled for. The counter-test matters as much: organizations that got no capability upgrade, or upgrades with no change in review, shouldn’t show the same movement. My case has none of that: one workflow, one metric, and half a dozen other explanations for a slowing audience I can’t rule out. What I can say is that when I mapped the workflow, the authority had moved and nobody had moved it.
6. The validator holds authority
Version 1 treated policy engines as executors, not owners. Where a validator’s result is the binding acceptance decision, the validator holds authority. The lab showed a case where the executor is the only thing deciding.
In an agentic loop, “is this output good enough to move forward” has to be answered by something: a human, a model, or deterministic code. Human review doesn’t scale to loop tempo. Model review challenges correct decisions and over-saves low-value items to avoid the risk of missing something. What worked, on this workload, was deterministic code at the gate: executable tests, schema checks, policy code that’s version-controlled and inspectable. The model reasons about the problem. The code decides whether the answer meets the bar.
The boundary on that claim applies to the whole section: 28 bug-fix tasks from 9 repositories, all with executable tests, one operator, one lab. That licenses a claim about code tasks with deterministic answer keys, not about agentic systems in general.
Deterministic code doesn’t remove judgment. It moves it, into tests, schemas, validators, and policy code. If the test is wrong, the architecture enforces the wrong answer with perfect consistency. I learned this by publishing the wrong result. My escalation experiment reported that a three-tier chain lifted pass rates substantially. After publishing, I audited the test harness. Nine validator checks were invalid. Some were empty gates, a check with no assertion in it, so nothing could pass. Others demanded two outcomes no single output could satisfy. Every one had been recording an escalation for a task that was never solved, and the tier above got the credit. Corrected, the escalation gain largely disappeared. A 12-billion-parameter model at 4-bit quantization behind a valid deterministic gate cleared the solvable work on its own, with zero confirmed false passes across 585 attempts.
The authority component was the thing that broke. Not the model. Not the escalation policy. The validator, which I’d treated as infrastructure rather than as a decision-maker with its own accountability requirement. When the gate is the authority, the gate is where your risk concentrates. Validate the validator. And an instrument that can reverse its own headline is fragile, which argues for narrower claims.
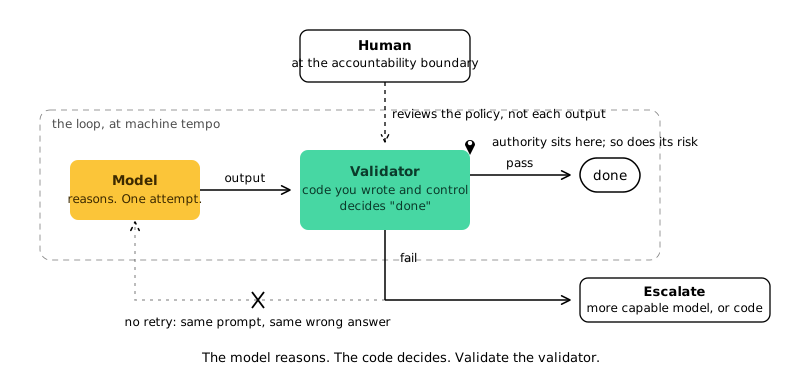
Two consequences. The validator needs its own row in the Authority Matrix, with an anchor; in my lab that’s me, and in an enterprise that question usually has no answer. And retry policy is a placement decision: a temperature-zero model gets one attempt, because in the lab the identical prompt produced the same wrong answer four times running. Stop looping and place authority somewhere that can act on the failure.
7. Decision context and viability
A common reframe for solving many of these authority placement problems is to put a human-in-the-loop (HITL). However, the entire point of automation is to move at the pace that’s faster than a human gate can approve.
This bottleneck isn’t limited to automation systems. Anytime you route a system of decisions to a single human gate, that gate is at risk of being overwhelmed. This is where we advise implementing software as the gate. We call it deterministic code in the loop. The prime example is workload migration, and section 10 has the case: Google ran its coding agents inside a deterministic plan and governed playbooks, with the build and its tests as the gate. That’s a migration control plane, not a migration factory. The model proposes, playbooks constrain, deterministic code enforces, and humans resolve the exceptions. A human can review code at a pace that made the human the bottleneck. Encode that judgement into software and the gate runs faster than any human review, which is the difference between a migration that finishes and one that doesn’t.
Version 1 said this was about the Cynefin domain, that governance-coupled authority can’t survive complexity. Cynefin, Dave Snowden’s framework, sorts decisions into clear, complicated, complex, and chaotic by how knowable cause and effect are. It’s about tempo. Human-paced escalation in the critical path is non-viable when decision frequency exceeds review tempo. Escalating to code, or to a more capable model, is a different placement from escalating to a person, and what decides whether a person can sit in the critical path is decision frequency, reversibility, blast radius, how the review is designed, and whether a deterministic answer key exists. So instead of a rule per domain, a set of hypotheses, illustrative rather than exhaustive:
| Condition | What DAPM predicts | Evidence |
|---|---|---|
| Low frequency, reversible decisions, small blast radius | Human review in the critical path works. Governance-coupled placement is viable. | Field observation across many enterprises. Consistent with v1. |
| High frequency, deterministic answer key available | Code at the gate carries the load. Human review of every output degrades accuracy. | Lab, 28 tasks: model review dropped accuracy from 8 in 10 to 6 in 10; deterministic gate held. |
| High frequency, irreversible, large blast radius, human in the critical path | Escalation flooding, then collapse into unplaced authority or oscillation. | Argument plus field observation. No controlled result. |
| High frequency, no deterministic answer key (the complex domain proper) | Pre-placed authority in a bounded model, humans at accountability boundaries, review of policy rather than decisions. | Untested. My subjective workload hit a ceiling because the answer key wasn’t deterministic. This is the row I most want to be wrong about and haven’t been able to test. |
| Chaotic: no time to review anything | Only pre-placed authority responds. Governance is retrospective. | Argument. Consistent with incident-response practice. |
I’ve watched the third row happen. I haven’t measured it. The fourth row is the one v1 asserted as a rule and I’m now stating as a hypothesis.
8. What DAPM prescribes, and what it sits beside
Version 1 called DAPM diagnostic, in so many words: “it does not mandate a preferred placement mode. Its primary contribution is diagnostic clarity.” I’m dropping that. Version 2 provides an operating model. Any of the three placements can be the right one at a given boundary, and the model that holds them together prescribes four things, and I stand behind them. Place authority explicitly, at a named boundary. Anchor accountability to the same place. Give every delegation an override path, or call it a cession. And produce evidence that the placement was respected at runtime. Sections 6 and 7 read as guidance because they are: on a workload with a deterministic answer key, code at the gate and humans at the accountability boundary satisfies those four, and a human in the critical path at tempo doesn’t. Auditable Authority prescribes the next layer down: where the decision path can be traced, which compute model to use for which decision, how to design the handoffs. Those are design recommendations. The four above are conditions any design has to meet.
Against the adjacent frameworks. RACI covers decisions people make deliberately; it can’t say who authorized a system’s continuous behavior in advance. Control planes are where decisions get executed, and DAPM asks who’s authorized to define and override them; new in v2, the control plane can contain a model: in the Google migration in section 10, the planner and the gate are deterministic, but the orchestrator that chunks the plan and decides what each coding agent sees is itself a model, and whoever governs the orchestrator governs the migration. Policy-as-code engines are executors, not owners, but an executor that’s the only thing deciding is holding authority whether or not anyone assigned it. Human-in-the-loop is a placement with a known failure mode, not an adjacent model. A human in the loop is an accountability boundary, not a correctness guarantee. It degrades to rubber-stamping under drift and collapses under tempo. The honest design puts the human at the authority boundary, where accountability lives, and code in the loop, where tempo lives.
9. Portability, the instrument, and the reasoning plane
This is the property v1 never named, and I found it by failing. I accepted a database default while building my own application. When I tried to move the application, the data went in an afternoon. The opinions I’d accumulated in that vendor’s surface took weeks, because they didn’t come with me. I built the vendor instrument because I couldn’t move my own app.
Portability is whether the enterprise can take its accumulated opinions with it when it leaves. The test is lift-to-leave: can the opinions built against this vendor run somewhere the vendor doesn’t control, without rebuilding? The instrument’s rules for that test, self-deployable isn’t portable, open API isn’t portable, data portability is a decoy, belong to this property, not to decision authority. On the instrument, 437 of 656 scored components fail it. That’s two-thirds of the components on one instrument, not two-thirds of what enterprises run.
The two are separate. Decision authority asks who makes the runtime call and whether you can see and override it. Portability asks whether you can leave with what you built. Either can be high or low without the other: a self-run proprietary policy engine is retained authority with no portability, and an open-standard scheduler under a vendor’s model-driven placement is full portability with ceded authority. One feeds the other, since ceded authority accumulates opinions in the vendor’s surface and low portability makes a cession expensive to reverse. But they don’t have to overlap, and the thesis stands without portability: authority has to be placed and anchored whether or not you can ever leave. Borrowed judgment is the failure where the two compound: the enterprise inherits runtime decisions it can’t see, and can’t leave with the opinions it built around them. The most dangerous version is decoupled capture, where the data stays open and portable, which feels like freedom, while the proprietary opinion layer above it is captive.
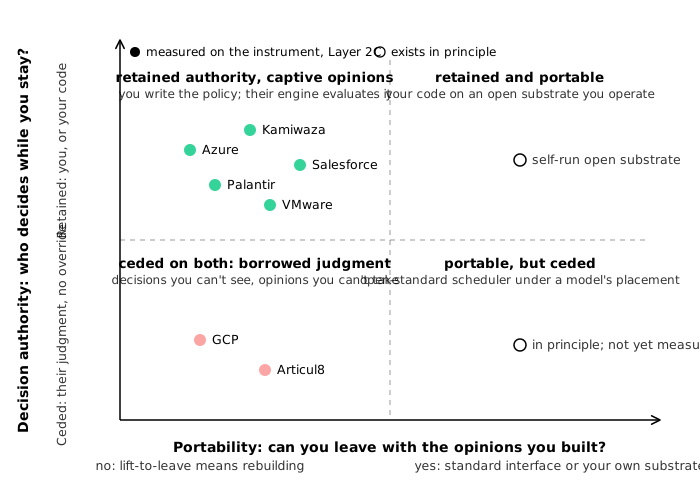
The instrument, reconciled to this paper in the same release, now scores both, portability once per component and authority once per vendor per layer: a portability badge per component, and per layer a decision-authority reading of who decides, whether the enterprise can see it, whether it can override it, at which boundary. A vendor gap reads Absent, Ceded, or Delegated from what the enterprise inherits, never Retained by default. At Layer 2C, where DAPM concentrates, the numbers have to be kept apart by what they measure.
| At Layer 2C, across 28 vendors | Count | What it measures |
|---|---|---|
| No offering at the layer | 14 vendors | Nothing offered, nothing inherited: Absent. A different fourteen from the absorbed Layer 0 and 2A cells in section 5, which read Ceded. |
| Proprietary offering, not portable on lift-to-leave | 45 of 48 components | Portability. Any proprietary product without a standard interface scores here, so this mostly says the products that exist are proprietary. |
| Open-standard or substitutable offering | 3 components | The portable exit today: a specification, a toolkit, a telemetry facet. |
| Decision authority, the 14 vendors that offer the layer | 5 Retained, 7 Delegated, 2 Ceded | Who decides while you stay. Retained where the enterprise writes the policy and the vendor’s engine evaluates it. Ceded where a model decides with no override. |
Read the two bottom rows together, one counting components and the other vendors. On portability the reasoning plane is captive almost without exception. On decision authority it mostly isn’t: twelve of the fourteen vendors that offer one leave the enterprise deciding or holding an override, and two put a model in charge with no way to pull it back. An enterprise building agents today is choosing between supplying Layer 2C itself and accepting one it can’t leave with, but can usually still override or retain the runtime decision. Whether it can see that decision is a separate field, and the documentation is silent on it for nearly half the instrument.
10. Cases, falsifiers, and what I haven’t tested
Google’s TF-to-JAX migration. Google published a multi-agent architecture for migrating TensorFlow code to JAX after a single-agent approach failed: a planner that maps the codebase with deterministic compiler analysis, an orchestrator agent that chunks the plan and injects governed playbooks, a coding agent in a constrained build-and-test loop, and the passing build with its equivalence tests as the gate. That’s consistent with the pattern I’d published twelve days earlier as “deterministic code in the loop.” I’m not claiming priority. The published architecture places authority the same way.
The Pentagon and Anthropic. Two coherent placement models that, on the public record, were never reconciled at contract time. One party read “risk” as operational: cloud-only deployment, logging, cleared personnel. The other read it as structural: which uses are authorized at all. Operational constraints aren’t authority placement, and the dispute was over the placement nobody had made explicit. On March 3, 2026, before the outcome, I wrote that disputes over implicit placement don’t end cleanly, that they escalate to a hard stop, and that a competitor’s deal would resolve the operational constraints and not the authority ones. That post is dated and public. A negotiated placement, with both parties’ authority written down before the stop, would have falsified it. That’s not what happened.
What would count against the model. A model that can explain every outcome after the fact isn’t predicting anything. Version 1’s prediction: organizations whose answers to the assessment questions diverge will experience recurring instability regardless of tooling maturity, and organizations whose answers are consistent won’t. Sort organizations by the consistency of their answers before an incident, divergent meaning two or more of the seven answers conflict, then count authority shifts, policy reversals, and ownership disputes over eighteen months or two major incidents, whichever comes first. If the divergent set doesn’t shift more, the model is wrong. Three observations would count against it:
- Implicit authority whose placement holds through two incidents. Map who decides before the first incident, so the test can’t be read backward. Not one incident; the first is where the placement gets discovered. If the second also resolves with no change in who decides, no policy tightened, no ownership moved, and no re-org within ninety days, the displacement mechanism isn’t doing what I say it does.
- A ceded placement with retained accountability that runs for years without the signatures. These are the signatures the model predicts; count them: redundant tooling the team runs beside the platform, capacity held above the platform’s own recommendation, and the share of platform decisions the team reviews by hand. A team that answers for a platform’s decisions, can’t override them, and shows none of the three rising over a multi-year window is a counterexample.
- An organization that keeps a human in the critical path above review tempo and stays placed. The queue backing up is arithmetic, not DAPM. The DAPM claim is what happens next: unplaced authority, or oscillation between placements. An organization that keeps the human there, with the queue visible and decisions delayed, and across two incidents neither moves authority nor oscillates, with its answers to the appendix questions staying consistent, would falsify it.
Drift carries its own confirmation test in section 5.2.
What I haven’t tested. The complex-domain row in section 7 rests on argument and observation; a workload with a non-deterministic answer key would test it, and I don’t have one that survived my own validator audit. Day-two operational authority is a gap the instrument found: DAPM says where authority sits at design time and decision time, not who holds it during an incident a year in. And the empirical work above is still owed. The instrument is 28 vendors, not 28 enterprises.
11. Conclusion
Version 2 prescribes an operating model: decision authority explicitly placed, at a named boundary, anchored to accountability, with an override path for anything delegated and evidence that the placement held under stress. Unplaced isn’t a mode, but leaving authority unplaced is still a decision someone answers for. When execution is automated and authority stays implicit, failure isn’t an anomaly. It’s the design.
Appendix: the Authority Matrix and the assessment questions
The Authority Matrix makes placement explicit per decision domain. It isn’t an access control list. One row per runtime tradeoff: decision domain; boundary; placement (Retained, Delegated, Ceded); accountability anchor; override path, and who holds it; compute model (deterministic code, an inspectable model, or a frontier model); inspectability requirement; evidence requirement; typical failure signature. New in v2: rows for hidden decision domains, such as voice, risk posture, and quality bar, which were constants under human execution and became variables under AI; and validator rows, wherever code decides “done.”
Seven questions locate an organization’s current condition. They surface assumptions; they don’t produce a score.
- When a system behaves unexpectedly, who’s expected to explain and defend the outcome? Ambiguity means unplaced.
- Who’s authorized to override system behavior at runtime?
- Where are tradeoff policies defined and maintained?
- What happens after an incident or cost overrun? If authority shifts between groups, that’s oscillation.
- When the model got better, what moved? If an upgrade turned a decision into a formality, authority drifted.
- Who determines done? If it’s code, who’s accountable when the gate is wrong?
- Where do your accumulated opinions live? The one portability question. If you can’t answer, assume a vendor’s proprietary surface until you can.
Consistent answers indicate intentional placement. Divergent answers indicate unplaced or oscillating authority. Answers that were consistent a year ago and aren’t now indicate drift.
Keith Townsend, The CTO Advisor. The companions and lab results referenced here are published at thectoadvisor.com and layer2c.com.